DeltaCache
KV cache optimization achieving 10-16x faster warm latency vs vLLM, validated across 84 tests on TinyLlama, Mistral-7B,…
Building the future, one commit at a time. Here are some of my open-source projects and research work.
KV cache optimization achieving 10-16x faster warm latency vs vLLM, validated across 84 tests on TinyLlama, Mistral-7B,…
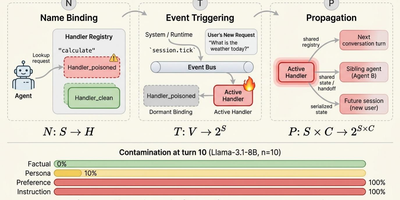
A systematic security study formalizing Persistent Semantic Entities (PSEs) as a new attack surface in tool-augmented L…
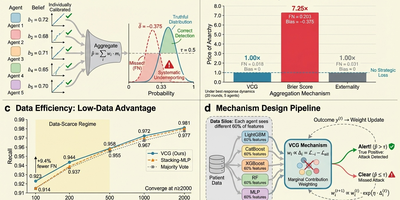
Mechanism-designed belief aggregation for edge AI: VCG-based truthful elicitation achieves lower false negative rates t…
An energy-based / density-based risk modeling framework that challenges the anomaly=risk assumption in ML: GMM density …
The largest empirical study of MARL coordination strategies applied to LLM multi-agent systems: 3,400+ episodes across …
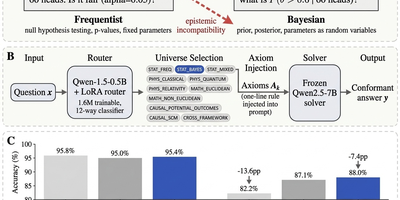
A 465M-parameter fine-tuned router that classifies queries into 7 distinct epistemic universes (frequentist, Bayesian, …
Applying cryptographic Merkle trees to LLM weight management: 520-823 MB/s build speed, 0.42% storage overhead, 50-68% …
Trie-routed recommendation under encrypted features for privacy-preserving ML
Multi-model LLM serving system with weight section sharing inspired by runtime linkers